One gateway between your people and every AI provider.
Janus Edge speaks the OpenAI API, so every tool your teams already use works unchanged — while each call is authorized by SSO, priced at the real rate, attributed to a person and a team, and recorded. Prompts never leave your control.
Governance you can actually see.
Not another black box between your teams and AI. Give people a clear view of their usage, and give administrators the controls behind it.
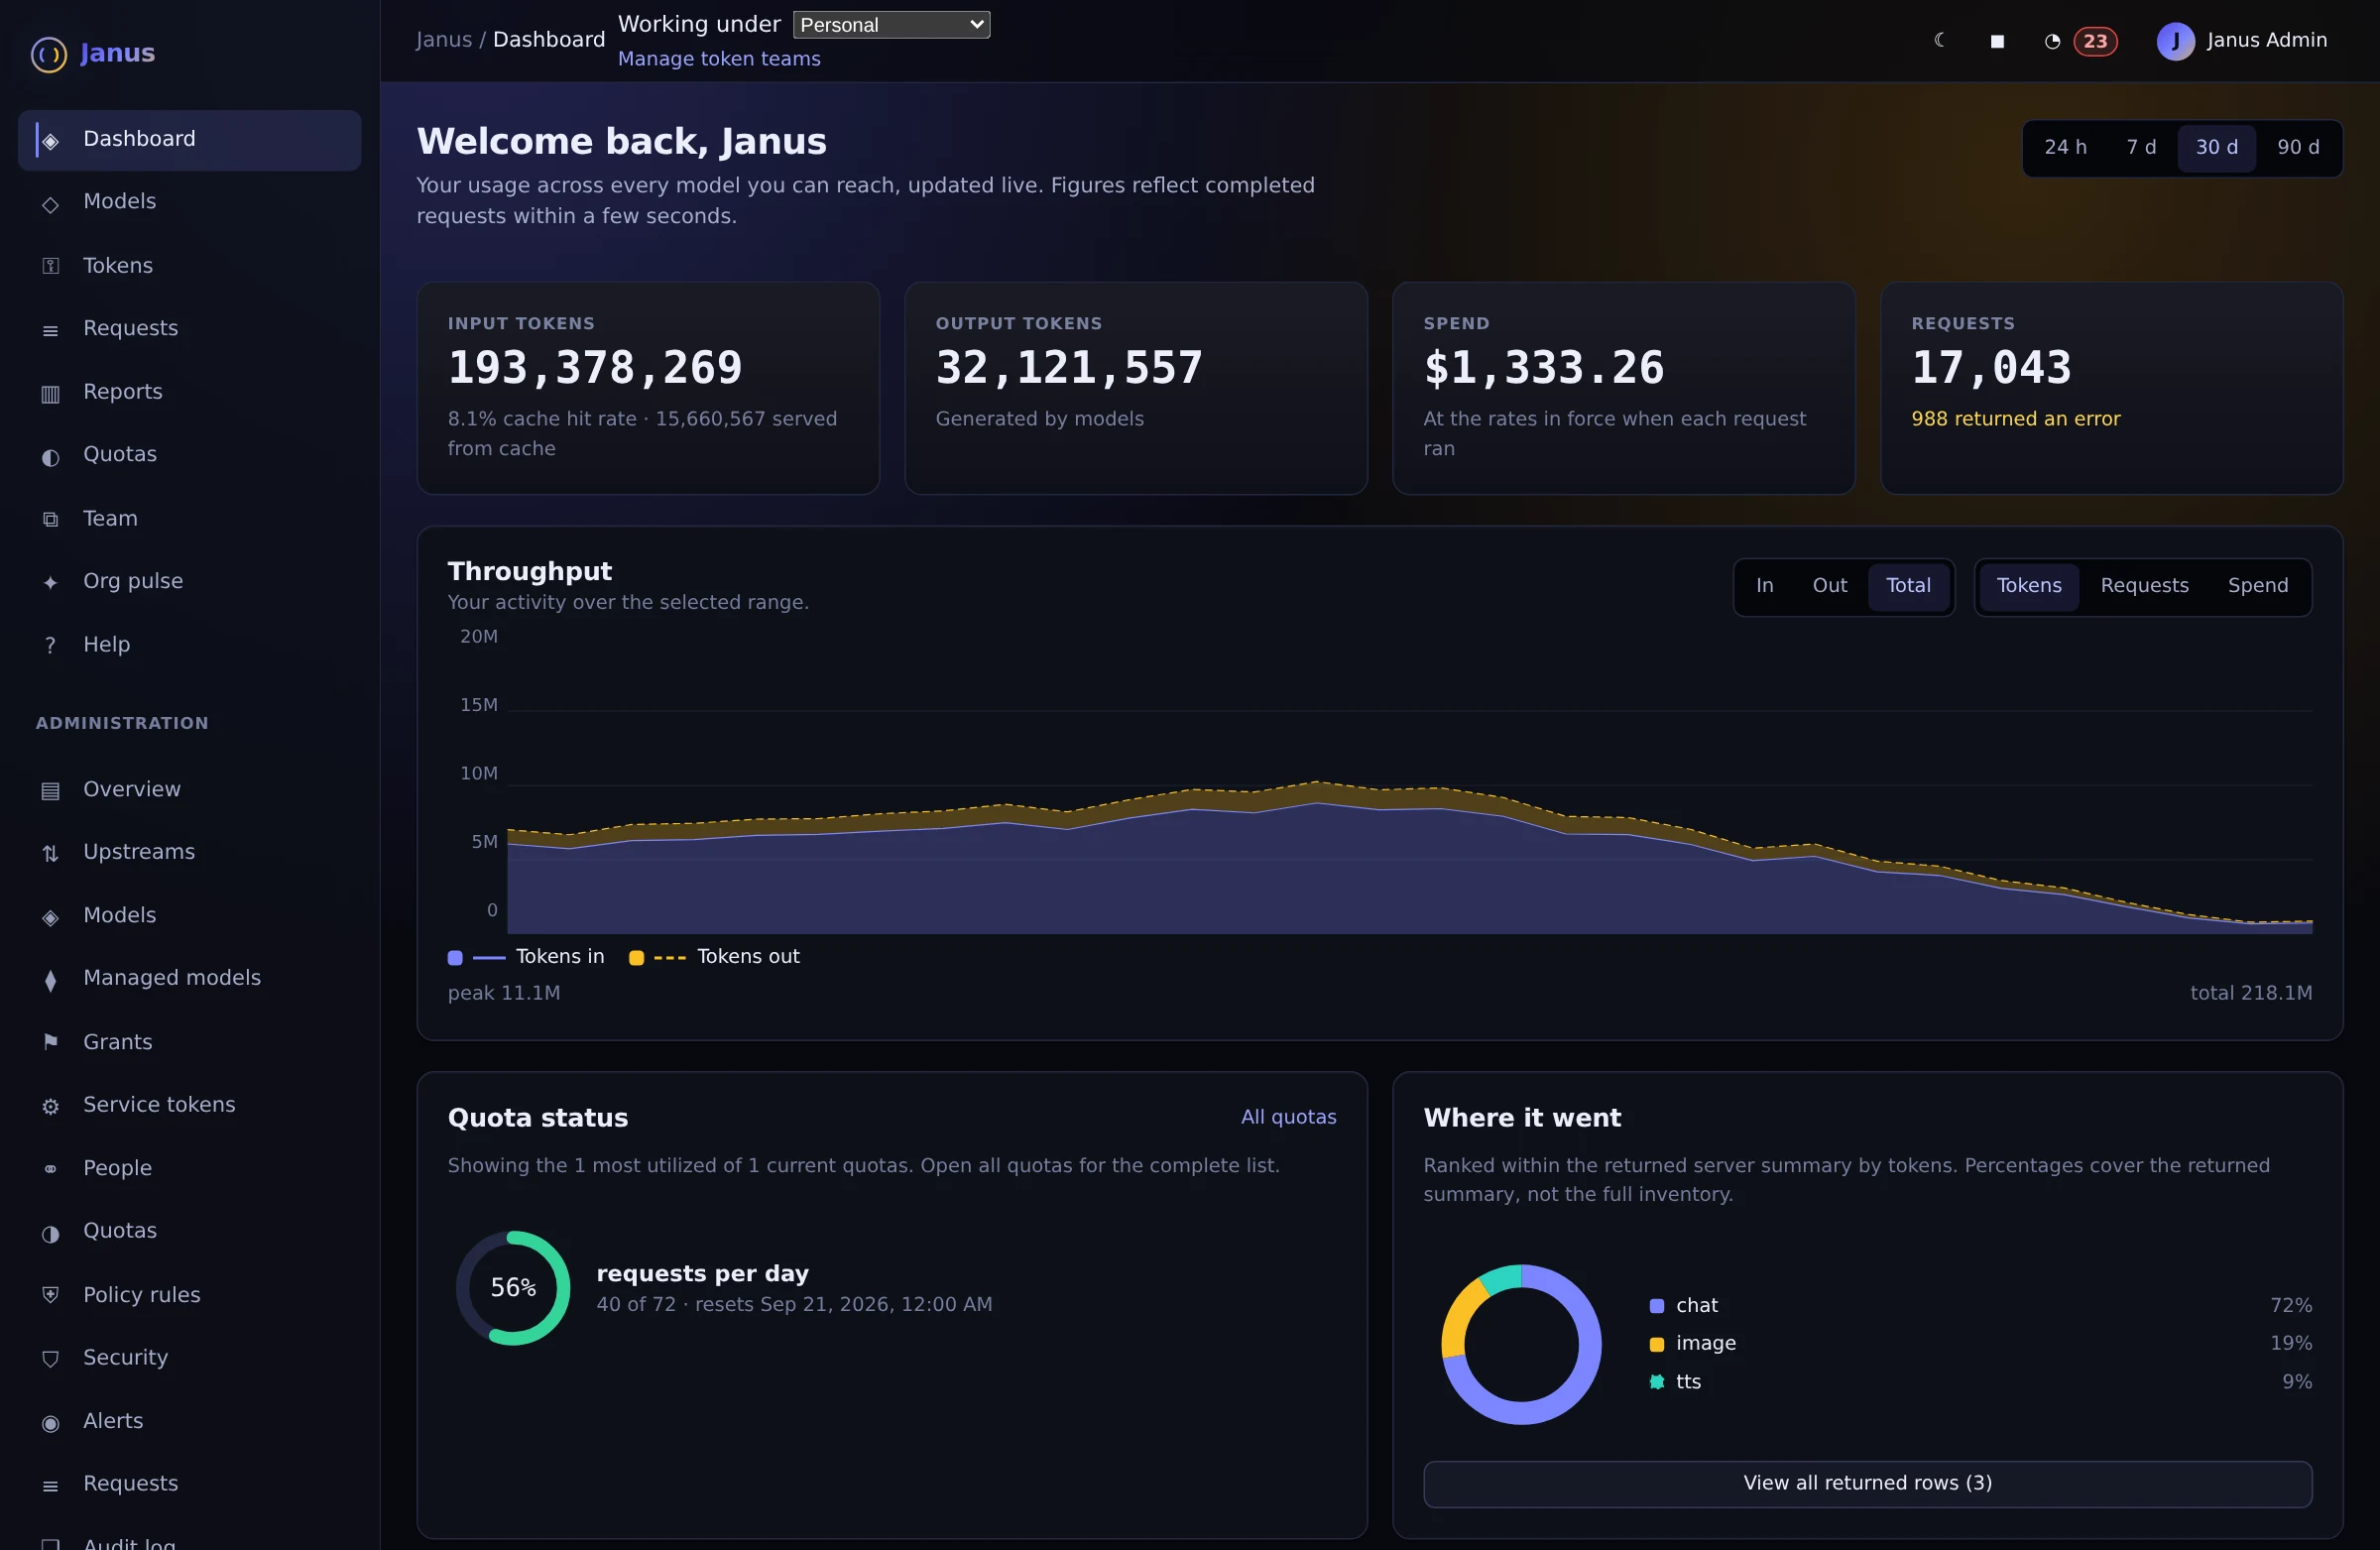
See usage trends, throughput, costs, and remaining quota without asking an administrator.
Actual Janus interface · Demo identities and synthetic usageInward face — your people
Sign in once. Use only what you're granted.
- OIDC with Okta, Entra ID, Authentik, Keycloak, AD FS
- Per-user, per-group, per-team model grants — signing in grants nothing by itself
- Self-service personal tokens, team service tokens, quotas with 80/95% warnings
- Any OpenAI-compatible client: IDEs, agents, notebooks, shells
Outward face — your providers
Every provider, one API, real prices.
- Managed model catalog: OpenAI, Anthropic, AWS Bedrock, Google Vertex, Ollama, TEI, any OpenAI-compatible server
- Chat, embeddings, images, audio, Responses, Assistants, files — streamed without buffering
- Usage and cost by user, team and token — reports and CSV export
- Passwords and tokens in prompts redacted or blocked before they leave your network
- Automatic fallback when a model or upstream goes down
Built for the questions IT gets asked.
Who is using AI, on which models, what does it cost, and what left the building? Janus Edge answers all four without storing a single prompt.
Explicit model access
GET /v1/models returns exactly what the caller may use. Grants compose across people, groups and teams; curated display names hide provider churn from users.
Metering that matches the invoice
Tokens in, out, cached and cache-written; cost at the rate in force at that moment; latency and time-to-first-byte; modality; finish reason; source IP. Per request, per person, per team.
Quotas and budgets
Cap tokens, spend or request count over calendar or rolling windows, per person or team, optionally per model. Refusal comes with a reset time, not a mystery.
Guardrails on the wire
Prompt-injection and content-safety classifiers (Prompt Guard, Llama Guard) run on ingress and egress. Observe first, enforce when you're ready.
Policy rules at the door
Compose block rules over client signals — user agent, headers, IP, forwarded-for — with AND/OR and negation. Evaluated before the request costs anything.
Observability you already run
Prometheus metrics, structured logs, append-only audit log, liveness and readiness probes, pre-built Grafana dashboards. Time-boxed troubleshooting captures when you need bodies.
Yours to run. Nothing to phone home.
Janus Edge is a single Go binary with the UI embedded. Install the Linux release or evaluate with Docker and source-built Compose; use embedded SQLite for a lab or plan PostgreSQL for production. Air-gapped networks are a first-class deployment, not an exception.
Free for teams up to 25. Priced per seat after that.
No sales call to get started. No per-token tax on your AI spend. Enterprise terms when you need them.